Blog

  • Are rich people kinder?

    In the movie Parasite, the poor family going through a tough time is sitting together talking about the rich family they just interacted with:

    Ki-taek: She’s so naive and nice. She’s rich but she’s still nice.
    Chung-sook: Not “Rich but still nice.” Nice because she’s rich, you know? Hell, if I had all this money, I’d be nice too!

    The stress from having to perform all the time to bring food to the table can put people in a bad state of mind, where they are less able to take a breather. Dealing with difficult people then does not come easy. Shelling out bullshit money to sort something is not an option.

    I don’t think though that rich people are kinder overall, in terms of giving. There are so many people who spend their lifetime building up their communities and helping others, who will not be on any list of rich people. Indeed, the richest donate a small fraction of their money … it is rare for rich people to disappear from the list of rich people.

    The analogy has been made that billionaires are like Smaug the dragon, hording their money for doing … nothing useful. They are withholding money from the economy, money that does not circulate as well as if it was with poorer people. Money only trickles up and then gets stuck there, and only through taxes on income and/or wealth, this effect is being made less severe.

    It’s not a coincidence that equality leads to higher happiness, not just for poor people, but also for rich people who have then less, because they do not have to fear the strong economic difference and stronger cohesion.

  • Replace “using AI” with “using computers”

    When cloud computing was a new, cool buzzword thrown around that no one understood, a shortcut was suggested whether it is the right solution:

    In any sentence, replace “in the cloud” with “on another person’s computer”.

    “Computing on the cloud” becomes “computing on another person’s computer”.
    “I backup my data to the cloud” becomes “backup to another person’s computer”.
    This makes it easier to weigh benefits – they provide more space, and provide maintenance, against drawbacks – they have your data and fully control the computer it sits on.

    Today, “AI” is thrown around as an all-encompassing buzzword. “Enhance your start-up with AI”, “AI helps prepare lawsuit”, “AI-written lawsuit contains mistakes”, “Fighting wildfires with the help of AI”, “Get data insights with AI”.

    Is there a similar shortcut that clarifies thinking?

    To expose overuse of the term “using AI” without meaning, I propose to replace it with “using computers”: “Enhance your start-up with computers”, “Using computers helps prepare lawsuit”, “Computer-written lawsuit contains mistakes”, “Fighting wildfires with the help of computers”, “Get data insights with computers”.

    This makes a few things clear: First, there are benefits to using computers because of their automatic data processing. This is not new with AI. Secondly, the replacement is effective at stripping away the mythical meaning of “AI” as an independent actor, removing the possibility to delegate ownership to it. Saying “my computer did it” sounds today much sillier than “my AI did it”.

    So, replace “using AI” with “using computers”. It reveals to you how little the statement by itself tells you.

    To seriously talk about AI, we have to unpack the term. In general terms, we are talking about methods that expand their capabilities with increasing data. Therefore to judge whether AI is good or not for an application, we need to find out:

    1. Where do the data come from, who made them?
      • Question 1 leads you to problematic biases in the training data that the AI inherits. It can also reveal copyright issues and whether the data producers are fairly compensated.
    2. By what performance metric do the claimants want to be judged?
      • Question 2 reveals what people value, and whether this aligns with your values.
    3. Is the performance better in that metric than the current method?
      • Question 3 reveals whether there was an improvement made so far, and may help distinguish vaporware from genuine improvement. The baseline may be another AI method, for example comparing LLMs to Markov Chains trivially reveals how much better LLMs are. Only very few analyses truly lack a baseline.

    Note that I did not include “what is the model?” – this is the least important technical detail.

    Questions 1) and 3) are often not made by the claimants, but reused. This is often not or extremely briefly described, reflecting how much time the AI developers spent on it. These three questions are essential for putting the AI claim into context.

    Some cop-outs:

    • If only similar performance is achieved, the AI developers often point to improvements in processing time, which should be added to the performance metric answer of question 2. It’s a valid goal to achieve somewhat comparable performance at much faster speed.
    • My pet peeve cop-out is “it has potential for improvement in the future.” This may be technically true, because models might learn with more training data. However, at least in a scientific and policy context a opportunity for critically and objectively examining the outcome, in context of the historical baseline, is being skipped.

    Demand from AI news articles to know the data origin, performance metric, and historic baseline.

    If they don’t give that information, replace “using AI” with “using computers.”

  • The hero of your story

    If you try confronting wrong behaviour, you are in trouble. When people hear they did something wrong, their mind first goes into the question of whether they are a malicious actor, then immediately rejects that idea as unfathomable, then rejects anything else you say as coming from a unreliable source.

    Understanding and working with the narrator

    In our minds, we are the hero of our story. Standing for truth, culture and goodness, treating others well. Osama bin Laden probably thought he is a hero defending his country, family and way of life first against the Russians and then the Americans. Maria Theresa thought she did well when sitting with those suffering instead of treating them, as those most suffering are most blessed.

    But how can you tell whether you are a good person? For starters, I find that good people do no think of themselves as good people. They think: I can do this better, there is still this issue to resolve, I’m not as nice as I could be. Bad people think: I’m good enough and if others have a problem, it’s their problem (and they can keep it to themselves). Our minds like to tell that we are the hero of our story.

    So how to work with others – and yourself – given these limitations of what our minds will accept as input?

    Working with the narrator

    When approaching others, it is best to first describe the problem you are facing, and how it affects you. People like to solve problems. Discuss how a situation is unfair – fairness is a good common interest. Seek common ground. Discuss aligned interests, and larger problems issues both of you face together. Avoid attacking holy cows and the identity of the other person. Instead, discuss behavior, its impact, and make a small suggestion how it could be different.

    In many cases, this does not work, at least not on the first try. Habits are too engrained to be changed at once by willpower.

    But it might surprise you how much people think about small criticisms. In that case, the story of wanting to be the hero can work in your favor.

    For myself, a guideline has been Kantian principle – treat others so that if everyone treated everyone else like this, would it be a good world? When I notice that I am starting to argue for exceptions for my actions … I should really rethink my actions.

    Questioning the framework

    In western culture, a mythical narrative is that of the knight, single-handedly facing a powerful enemy, and against all odds, defeating them.

    That narrative is reflected in many movies as well. While it might be motivational, it is also problematic: It promotes selfish and self-crediting behavior, downplaying the credit of others (who gave you that sword?). It makes others helpless non-actors that must be saved, and demands that they give thanks to the hero. It is really not the collaborative approach of modern work culture requiring a team effort of complementary strengths.

    A further problematic aspect is that of self-sacrifice in the final struggle. It is quite absurd, how Hollywood movies regularly let the hero destroy their enemies. If they also succumb, they are celebrated solemnly as having done the right thing. At the same time, western culture finds Islamic suicide bombers gross and uncultured. Self-sacrifice is expected in many work places to the point of burnout, and expected of mothers (but not fathers) – mothers having hobbies or interests besides their children raises eyebrows.

    Questioning narrative frameworks, especially deeply engrained ones, is difficult, and requires a equally captive story and repetition. Rational thought alone won’t do.

    Another approach to destroying frameworks is to abuse them into comical absurdity. Short-term life hack for women: Create mini-missions for a man in your life and tell them that if they accomplish the victory they are your hero.

  • Publication time in astronomy vs statistics

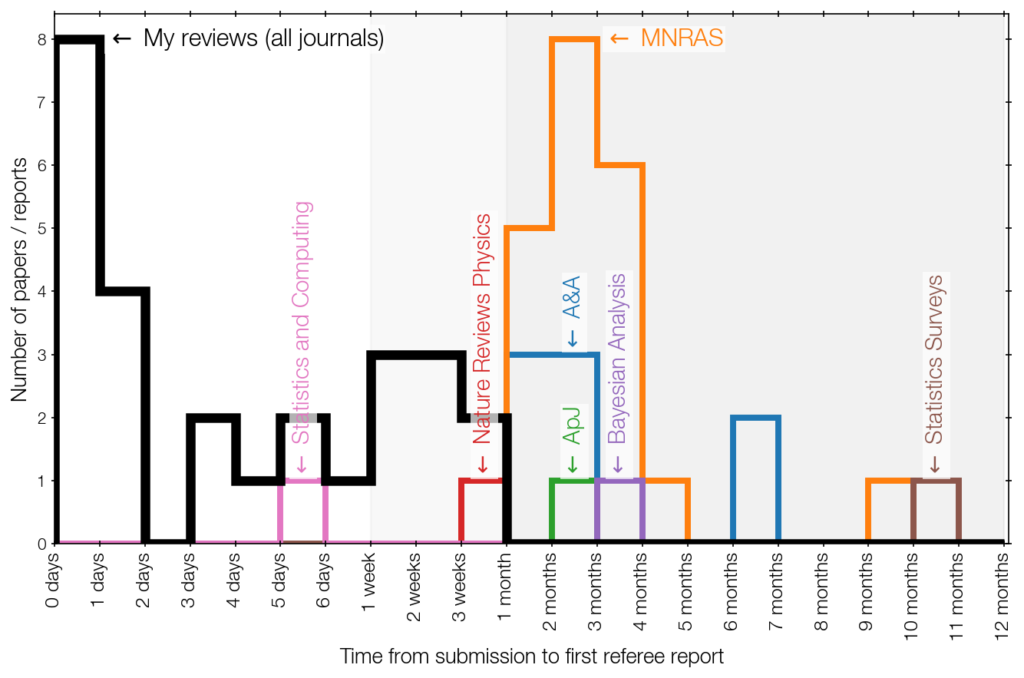
    After submitting a paper to an astronomy journal like MNRAS, ApJ, A&A, PASP it is quite typical to receive a referee report within 1-2 months.

    A search of my emails confirms this – green, orange, blue histograms are astronomy journals:

    For statistics journals, the waiting times can be much longer in my experience. For Statistics Surveys, and another paper not shown in the above, I waited for almost a year! That’s quite a shocking cultural difference. What do statisticians do all day?

    I also plotted in black how long I take between receiving a request for reviewing and submitting the review. I typically do it on the same day or the next.

    I am apparently not a typical reviewer!

    Oh – this might be a way to identify me as your reviewer 🙂

    (more…)
  • The top and bottom halves of data analysis in astrophysics

    There are two approaches to analysing data, which I will call the bottom and top half.

    Bottom half

    Look at images and data by eye. Discover anomalies and outliers. Argue primarily qualitatively. Potentially preprocess the anomaly-finding with machine learning.

    It’s a good approach for junior scientists to start looking at data (a) and understand its artifacts and limitations. However, the by-eye approach does not permit quantifying false positives and false negatives.

    The bottom half brought us the hunt for high-redshift galaxies and quasars, reddened quasars, the most luminous galaxy, the most massive black hole, Voorwerpjen, etc. etc.

    The bottom half is great for discovery of extremes by appearance.

    The bottom half approach can only search across data space, not by physical parameters. After discovery, to get physical information for the discovered system, one then switches to another type of analysis.

    Top half

    Use a physical model to fit data. Build a model that can explain the data. Quantify, including the uncertainties. Distinguish two competing physical processes.

    This can be achieved with (hierarchical) Bayesian models combined with advanced inference engines (nested sampling and dynamic Hamiltonian Monte Carlo), and more recently, perhaps, with simulation-based inference.

    Combining both halves

    Some research projects can use only the bottom half, discover something and argue qualitatively. It’s somewhat quite easy to do this: You just project the data into one or two dimensions – for example looking at color – and start visually inspecting the extremes. Slightly fancier versions, but conceptually the same, are to look at a latent space, for example produced by UMAP (or the older T-SNE), or an auto-encoder. These latent spaces are usually meaningless themselves, and randomly oriented so that a retraining gives something completely different. I’ve seen many researchers get lost in over-interpreting the shapes in latent spaces.

    To go beyond discovery and qualitative existence proofs, one needs the other half: An approach that models the demographics, placing the extremes in context, and connecting the physical space to the data space with a physically meaningful model.

    Admittedly, I call this bottom and top half to make myself and my focus on the top half feel superior. However, the top half can also not exist without the bottom half: You cannot do a blind, automated model fitting without investigating data artifacts, and careful validity checks. You need detailed analyses of individual, nearby galaxies to understand surveys of the distant Universe. So only the two halves make a whole.

  • Reliability

    Three decades ago, the word was “four nines”.

    Internet providers and company server administrators would take pride to deliver a service that was working 99.99% (four nines) or 99.999% of the time,. In German and Swiss culture, reliability is highly valued and this has been a differentiating factor, for example for automobiles and watches. Chains such as Starbucks largely build on your feeling of security of knowing exactly what you will get if you enter.

    Removing uncertainty from an uncertain life has value.

    A bit after the 2000s, reliability stopped being a focus for software services. Github, a key infrastructure component for many people to the point that people stop working when Github is down, does not promise four nines or make any reliability commitments. From EU, US to Chinese markets, towards the latter it is much more acceptable to customers that exciting new software is comes with bugs that need to be ironed out later. This results in quicker delivery timelines and innovation.

    So it is not necessarily a bad thing that it has become more acceptable that software and software services are unreliable. Building reliability takes continuous optimization over time and focused effort. The trade-off of reliability is dynamic adaptation to new markets and changed situations.

    Say for example a colleague sent you a file and its not quite the format that you can use. You write that short script or command line command (sed, awk) once, use it, verify that the output works, and never use that script again. You will not get exactly the same file format again. You do not need to support all possible variations of file formats that might arrive in the future.

    Data pipelines in research are much like this. It took me time to stop building generic multi-purpose frameworks. Most software developed in research projects is ad-hoc data transformations. By definition, research deals with something new. For the specific project, you mangle data from one form to another. You verify that it is all correct. The data pipeline specific to the project will likely not be reused in exactly the same way for the next project, because the next project is different, the exact form of the input or output, or the validity considerations will not be the same.

    Now elements of the script may be reused. We identify the commonalities. If many scientific projects benefit, the community rarely but surely invests into building a reliable, reusable data reduction pipeline. The process to get there is non-transparent and messy, but some truly impressive pipelines exist that qualify for four nines.

    For machine learning-based projects, reliability is both in and out of fashion. In principle, the starting point is great: Projects start by defining a metric to optimize (loss function). That is already a great exercise for defining what you care about, which is often otherwise left unspoken. That said, many AI-based research presentations leave me with the question: “Does it work?” and “Can I rely on it?”. Often the answer is no, formulated by the authors positively as “not yet”, and more specifically, with the phrase: “While it is not yet as good as previous approaches, our machine learning approach has the potential to outperform these in the future.” There is value in trying new approaches and it requires effort, often not achievable in a single 3-9 month project cycle. Maybe this is due to my cultural background, but I think we can be more ambitious on the standard we set for ourselves.

    You can see the lack of reliability also in a very basic metric: uptake. How many people use an AI-based tool productively? If it is not reliable enough, this will show up as a lack of citations.

    People might still talk about software that is not useful. On the one hand, this may be AI hype specific to a particular technique. This has also existed before. On the other hand, it may be genuine interest in a project in the future may opens a new type of analysis that has been accessible before. This is how new technology has always evolved – rather than improving established ways of achieving goals, focus on how new technology enables achieving different and new goals that could not be considered before.

    Despite being less visible, four nines are still important for non-customer facing backend software, but also for customer-facing software. If you want to dictate your email to your computer, or command a device, what error rate would be acceptable to you? If even 1-2 out of 100 sentences is wrong, and you have to work around the errors, the illusion of a smooth human-computer interface is broken. Take-up on voice-control is poor because it is more frustrating than a 100% reliability keyboard.

    For chat-based LLMs and AI agents, the threshold we accept seem to be astonishing low. You might get a useful answer only 20% of the time, but when it works the rush of excitement is enough to keep you going. The randomization is addictive, feeling like being at a slot machine for programmers. That said, makers of LLM optimize for exactly these performance reliability metrics, so we are seeing continuous improvements. The data driven approach means the reliability potentially reachable is certainly limited by the amount and purity of training data. The ceiling for reliability is, essentially, unknown.
  • The meaning of life

    Creating something is a form of expression. You put a piece of yourself into it. Effort, time, but also a piece of your craftmanship and thinking about how something should ideally be. For many artists, the act of creating their art is so important that giving it up would give up an essential part of their being.

    These days, software engineers are rediscovering just how important crafting software is to their identity. It has been true before that for many professional software engineers, their weekend hobby project was … creating software. For fun. It gives purpose to them to create something useful. Many times, the software is useful to exactly one person, and that’s okay.

    The advent of large text interpolators has created a scare among those that deal with text-based work. It is now quite possible to recreate software “from scratch”, if one has a technical specification, and a test harness. There are a few misunderstandings, however.

    1): Firstly, such a reproduction is a derivative work, because the LLM has been trained on all of github, often including the specific code and thus interpolating copyrighted work rather than extrapolating.

    2) Secondly, reproducing someone else’s work with LLMs does not build the skill to adapt the work to new specifications. Yes, you can adjust the prompt, but as anyone who works with LLMs knows while it feels cool and fast, it is neither a stable nor efficient workflow, you have to edit code yourself as well. Earlier this year I “lost control” over a software repository by letting an LLM make too many edits, to the point where I was unfamilar with the code and could not debug the mess any longer. I had to backtrack, delete large parts, and with discipline, built by hand the complex code that is not interpolatable from LLM training data.

    3) Thirdly, I have serious doubts many AI-created software packages will still be maintained after a year. Interest of the “creators” is largely not long-term in the domain, but rather with the AI toys.

    I still have hope that there ultimately is a feedback loop of “Has this person delivered value?” Not, “Has this person appeared to have delivered value?”, not “Has this person done something trendy?” but looking back at the created change in the bottom line.

    For me, there are three lessons:

    1) Creation gives purpose. From AI prompting pride in the creation cannot be generated, even if you give yourself titles like “Prompt engineer”. Effort is a key differentiating factor.

    2) Creation builds domain expertise. You can confidently argue about fine points. If you build with LLMs, your knowledge is shallow. Critical reading about a topic, including the background not directly relevant to a task at hand, is key here for retaining a big picture view of where a project should go.

    3) Computing and Society: Only by working and listening to people can you build something that matches a real need. One of the reasons why I departed from classical IT is that I felt many tools were built by software engineers for improving the lives of software engineers, but lacking a bigger goal. With AI, even if coding were to fall away as a skill, the skill to identify requirements through dialogs and embedding a solution with people remains an essential software engineering skill.

    I find research software engineering quite fulfilling. I build tools that are used by myself and my colleagues to investigate the Universe. I call them software telescopes. Could I find similar purpose in another domain? Probably. Could I find purpose in life without building something and putting my heart into it? Maybe not.

  • Garching

    Today, we walked 100 meters from home to the park, set up a inflatable couch, leaned back and watched the Perseid meteor shower 🌠 . It was beautiful. Garching is one of the very few places on Earth where you can see the night sky clearly, and work as an astronomer.

    Garching is a small city, but it is big enough that it has one of everything you need.

  • An open door policy

    The saying goes that those who keep their office door open have a better career. I do not have hard evidence supporting this, but I know that some people shut themselves off in their offices and have then not had a lot of exposure or opportunities.

    Chance encounters are quite powerful. “Just a quick question …” through an open door opens the door for something else.

    When talking with junior scientists, especially when genders are mixed, keeping the door open is good practice. It avoids the hint of any suspicion that something improper could happen in a meeting. It opens yourself to being audited by a passer-by. This can provide safety to the junior scientist as well. When it is exceptionally noisy, I ask for permission from the junior scientist whether it is okay if I close my office door.

  • Eye contact in academia

    Eye contact is important when giving a talk. If you find it unpleasant to look people in the eye, you can look just above the audience and will achieve the same effect of the audience feeling seen, and you not just bumbling to the screen.

    Eye contact can be unpleasant to give but also to receive. Personally, I cannot hold eye contact for a long time, but several close colleagues struggle with this even stronger. It is perhaps related to being on the spectrum, perhaps personal preference, perhaps how socially safe you feel in the situation. I curious to what degree inability to hold eye contact limits people’s social status.

    In any case, it is important to realize how important eye contact is for the other person and calibrate accordingly. If my opposite needs it to feel trust and a human connection, I give a bit more than feels comfortable to me. If I feel they cannot stand it, I avoid long eye contacts and make by gaze wonder across the room while I go on a tangent in the conversation.